
When coding agents are deployed in data centers, the challenge is no longer as simple as a chat window. An agent fixing a bug across a dozen files must repeatedly read code, search references, run tests, and accumulate more and more historical information.
When thousands of agents work this way at the same time, operators discover that servers may still be running, but sustainable concurrency becomes increasingly tight. Some requests wait a long time just to output their first token.
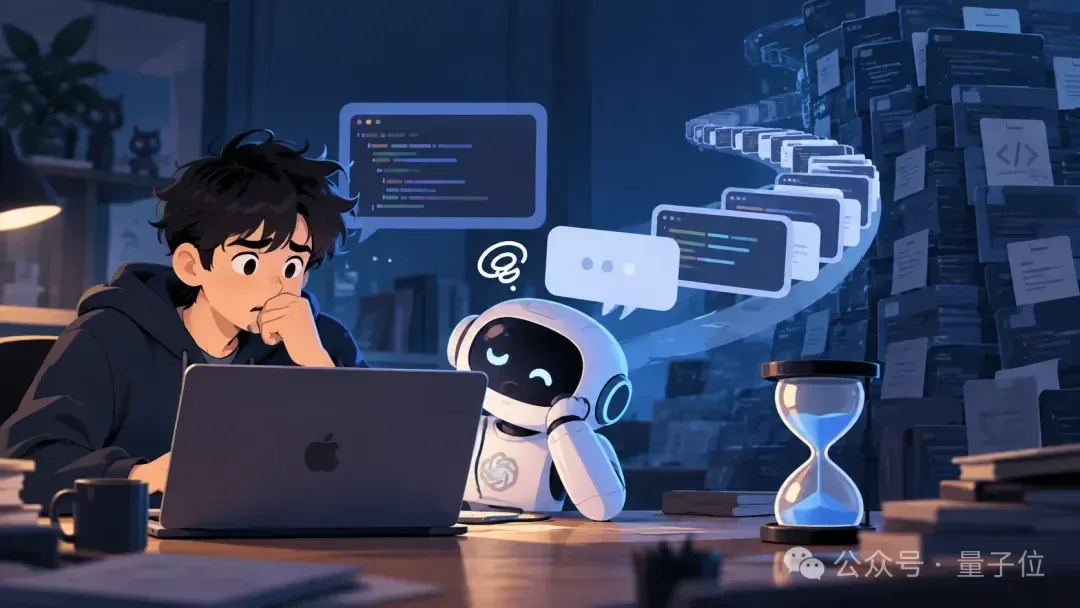
The root cause is memory. Every time a large language model generates a new token, it must keep using earlier context. The system caches already-computed intermediate results—this is KV Cache. The longer the session, the thicker this notebook becomes.
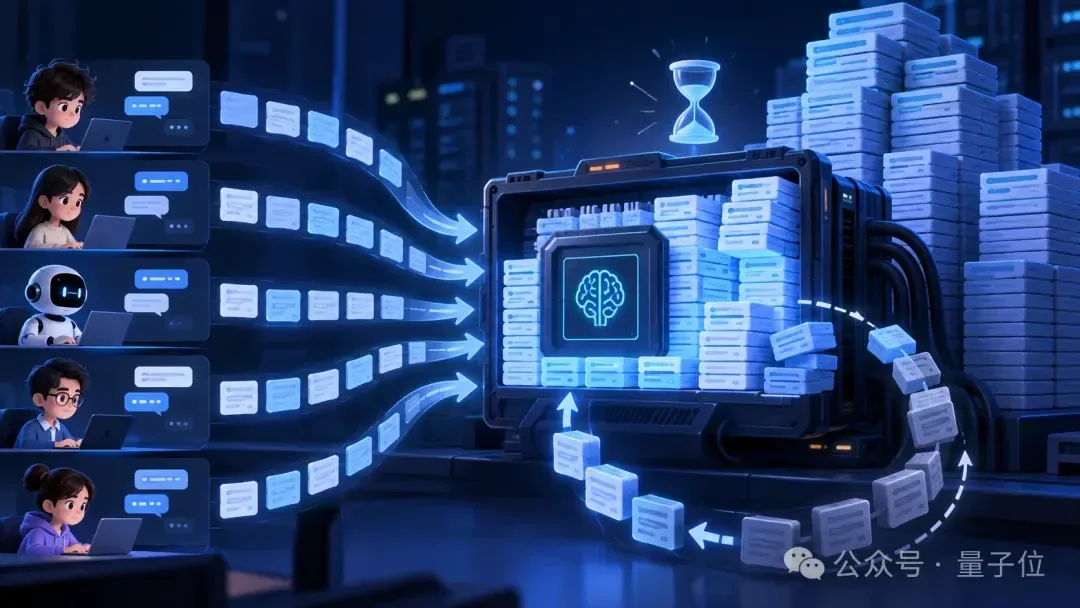
For Qwen3-8B, calculated in BF16 or FP16, each token corresponds to about 147KB of KV data. Extrapolated to a million-token context, the cache can reach about 147GB. Once VRAM cannot hold it and some cache is evicted, the next round must redo Prefill.
The breakthrough idea is storage-for-compute: hot data stays in GPU high-bandwidth memory, cooler data moves to CPU-side DDR memory, and colder data sinks to SSD or remote storage. CPU-side management logic coordinates it all, allowing cache to be reused as much as possible instead of repeatedly recomputed.
Intel has built tiered management and hardware compression around KV Cache, using dedicated QAT acceleration units to offload compression and decompression, and rearranging storage formats to improve compression gains. In Intel's tests, at an 80% cache hit rate, KV Shrink delivered up to about 5x faster time to first token (TTFT) versus the native vLLM baseline. StarWar Technology's direction