
Anthropic has reportedly chosen Nasdaq as its listing venue, with a public debut possible as early as October this year. The scale of its fundraising is said to be comparable to, or even larger than, that of SpaceX. Earlier market rumors suggested its valuation target could reach the $2 trillion level. If realized, this would mark another capital feast for the AI industry. Yet the timing is delicate: the company’s CEO had just published a long essay urging the industry to slow the pace of frontier-model capability improvements, only for reports to emerge that Anthropic is accelerating its IPO push.
Viewed together, the contradiction points to the same reality: compute is extremely expensive. According to public information, Anthropic still faces more than $100 billion in cloud-service commitments over ten years, an expanded TPU collaboration with Google and Broadcom, and reliance on external compute clusters. Each represents long-term cash-flow consumption, making an IPO an important path to replenish capital.
Revenue growth is equally striking. Multiple media outlets, citing sources, say its annualized revenue run rate has risen rapidly from around the $1 billion level to the tens of billions of dollars level in just over a year. That slope shows that enterprises’ willingness to pay for AI is real, but it also means token consumption and inference costs will scale in tandem. The faster revenue grows, the higher the demands on compute supply and cost control—and the more the sustainability of the business model depends on compute efficiency.
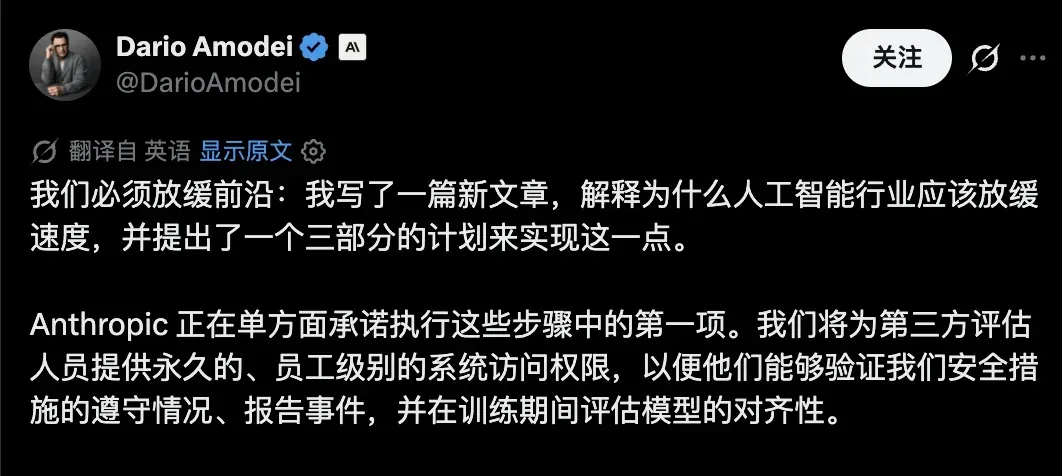
This also explains the other side of the “deceleration” argument. When model capabilities are determined by humans, the pace can be controlled. But when recursive self-improvement, automated evaluation, and agent collaboration begin to participate, capability gains become increasingly driven by the system itself. At that point, emphasizing safety and alignment does not contradict continued expansion of compute investment—both require time and resources, and both point to the same goal: turning uncontrollable acceleration into manageable engineering.
This aligns with StarWar Tech’s focus on GPU compute platforms and compute scheduling. Whether for large language model companies or enterprise users, the real challenge is not simply owning compute, but making it schedulable, measurable, and orchestrated by priority. Organizing distributed GPUs and heterogeneous resources into a unified resource pool—and allocating training, inference, and business workloads by cost and timeliness—can help balance expansion with cost discipline.
For the industry, the oscillation among leading companies between “hitting the brakes” and “grabbing compute” shows that AI competition has entered an infrastructure phase. Beyond models, data, and talent, whoever can obtain and use compute more efficiently is more likely to maintain pace in long-term competition. The enthusiasm of capital markets will ultimately have to be redeemed by compute efficiency and commercial returns.
Calling for prudence while accelerating financing seems contradictory, but it is normal in the compute era. When compute becomes the underlying variable for valuation and rhythm, the real dividing line is not who speaks loudest, but who can use resources steadily and calculate clearly.